Copilot Studio: Speed Up and Cut Costs
SharePoint & PowerApps MVP - SharePoint, O365, Flow, Power Apps consulting & Training
Optimize Copilot Studio agents for speed and cost with SharePoint hints via Microsoft Copilot and Power Apps
Key insights
- Copilot Studio: The video demonstrates making Copilot Studio agents faster and cheaper by giving clearer, task-focused instructions.
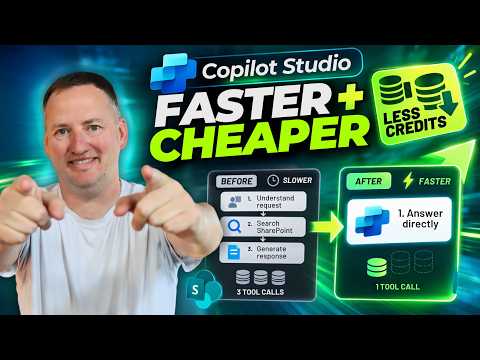
Shane Young shows a SharePoint-connected example where better prompts cut a three-step request down to one, reducing wait time and credit use. - Agent instructions: Tell the agent exactly which SharePoint site, list, and fields to use so it stops searching for context each time.
Clear instructions prevent redundant lookups and speed up responses. - Reduce tool calls: Filter queries to return only the rows and columns you need and avoid unnecessary intermediate actions.
Fewer tool calls mean less reasoning, lower latency, and fewer credits consumed. - Skills and persistent memory: Move repeated logic into reusable Skills and store stable context in persistent memory.
This shifts work out of runtime and makes agents more efficient on repeated tasks. - Rebuilt authoring and orchestration: Microsoft’s updated studio provides a single-page authoring flow with Build, Preview, Evaluate, and Monitor tabs and a new orchestrator for multi-step and multi-agent work.
That reduces authoring friction and improves reliable execution. - Cost and model choices: Choose lower-cost models and tune prompts for minimal calls; monitor Copilot Credits and trade off speed, quality, and cost.
Smart model selection and fewer actions drive meaningful cost savings.
Introduction
In a recent YouTube video, Shane Young [MVP] demonstrates practical ways to make Copilot Studio agents run faster and use fewer credits. He shows a hands-on example using a simple agent connected to a SharePoint MCP server, and then explains what the agent is actually doing behind the scenes. Consequently, the goal shifts from merely getting correct answers to getting them with less unnecessary work and lower cost. This editorial summary highlights the techniques, tradeoffs, and challenges Shane outlines so teams can apply them in real projects.
What the video walks through
First, Shane builds a straightforward agent in Copilot Studio and runs it against a SharePoint list to observe the runtime behavior. Then, he progressively refactors the agent’s instructions to reduce the number of internal tool calls and reasoning steps, moving from a three-step flow to two steps and finally to a single step. By watching the agent perform each step, he identifies where redundant lookups and broad data pulls are costing time and credits. As a result, viewers see both the practical changes and the measurable effects on performance and consumption.
Along the way, Shane emphasizes the importance of giving the agent explicit context about the target SharePoint site, list, and schema so it does not spend cycles trying to discover that information every time. Moreover, he demonstrates how filtering the data at the source reduces the payload the agent must process, which in turn decreases reasoning overhead. Accordingly, fewer tool calls lead to less waiting and lower credit usage. This makes the agent both faster for users and cheaper for organizations to operate.
Practical techniques shown
One primary technique Shane recommends is to include known site and list identifiers in the agent instructions rather than letting the agent search for them dynamically. By contrast, letting the agent rediscover resources on every request can trigger extra API calls and expensive grounding operations, so giving it precise location context cuts unnecessary work. In addition, he illustrates how to apply server-side filters so the agent retrieves only the rows it needs instead of pulling whole lists. Therefore, less data retrieval reduces both latency and processing costs.
Another technique is to minimize the agent’s reasoning steps by simplifying prompts and focusing the agent’s task. For instance, instead of asking the agent to decide which list to query, the instructions can directly state the target list and the expected fields. Furthermore, Shane discusses how some responsibilities belong in persistent Skills or prebuilt components rather than in ephemeral agent instructions, because Skills can be optimized and reused without repeating expensive operations. Consequently, this separation can improve maintainability while reducing runtime expense.
Tradeoffs and technical challenges
While these changes yield clear speed and cost gains, they also introduce tradeoffs that teams must weigh carefully. For example, hard-coding site and list identifiers improves performance, but it reduces flexibility if the underlying data model changes frequently or if agents must work across many tenant sites. Therefore, teams must balance stability and adaptability when deciding what information to bake into instructions versus what to discover at runtime. In short, a faster agent may be less resilient to changes unless supported by robust monitoring and update processes.
Another challenge is organizing complexity when agents need to collaborate or orchestrate multi-step workflows. Although Microsoft’s recent improvements add multi-agent orchestration and more model choices, orchestrating multiple specialized agents raises questions about state passing, error handling, and cost attribution across agents. Moreover, selecting lower-cost models can speed up responses but might reduce answer quality, so teams must define acceptable quality thresholds. Thus, building efficient agents involves juggling performance, reliability, and result fidelity.
Impact and recommendations for builders
For builders experimenting with Copilot Studio, Shane’s video offers a practical recipe: start simple, observe runtime behavior, and then incrementally move stable responsibilities into reusable components. Moreover, teams should add focused instrumentation so they can measure which calls consume the most time and credits and then optimize those hotspots. By doing so, they maintain a clear path from prototype to production without sacrificing oversight.
Finally, organizations evaluating Copilot agents will benefit from defining policies for when to prefer runtime flexibility versus static configuration, and from training authors to write concise, context-rich instructions. In addition, investing in a few optimized Skills that handle common, expensive tasks can lower long-term costs while preserving quality. Ultimately, Shane’s guidance helps teams make informed tradeoffs between speed, accuracy, and maintainability.
Conclusion
Shane Young [MVP] delivers a focused, actionable walkthrough showing how clearer instructions and targeted design choices make Copilot Studio agents faster and cheaper. By giving agents precise context, filtering data at the source, and moving stable logic into reusable components, builders can reduce unnecessary tool calls and credits. However, they must also manage tradeoffs around flexibility, update costs, and model selection. Therefore, teams should test changes incrementally, measure impact, and balance short-term gains with long-term maintainability.

Keywords
make Copilot Studio faster, Copilot Studio performance tips, reduce Copilot Studio costs, optimize Copilot Studio, speed up Copilot Studio deployments, Copilot Studio cost optimization, scale Copilot Studio efficiently, Copilot Studio performance tuning