- All of Microsoft
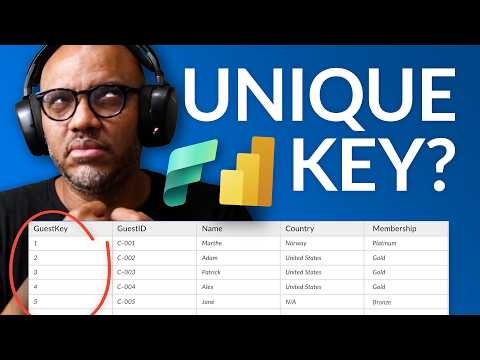
Azure Synapse: Surrogate Keys Today?
Microsoft expert on when surrogate keys trump natural keys to preserve history in Power BI and Fabric
Key insights
- Surrogate Keys vs Natural Keys
Surrogate keys are warehouse-generated IDs with no business meaning. Natural keys come from source systems. Use surrogate keys deliberately when you must preserve stable relationships or track row versions over time. - When to use surrogate keys
Prefer surrogate keys for history (like SCD Type 2), for conformed dimensions across multiple sources, and when source keys can change or collide. If a dimension is tiny, single-source, and static, a durable natural key can be acceptable. - Key benefits
Surrogate keys keep historical accuracy, simplify joins in fact tables, improve performance with small integer joins, and isolate the warehouse model from source changes. - Microsoft Fabric implementation note
Microsoft Fabric currently lacks native IDENTITY/SEQUENCE support, so teams must build key-generation pipelines. Common workarounds include using ROW_NUMBER() in batch loads, a dedicated key table, or deterministic hashes where appropriate. - Recommended design pattern
Store the source business key for lineage, generate and store a separate surrogate key as the primary warehouse ID, use that surrogate in fact-to-dimension relationships, and only create new surrogate rows when an attribute change requires a new version. - User-facing guidance
Keep surrogate keys internal to the model and hidden from report consumers. Design your semantic model so end users see meaningful business attributes while the warehouse uses surrogate keys to preserve correct history and joins.
In a recent YouTube video, Guy in a Cube examines a long-running debate in data modeling: whether to use natural keys or surrogate keys in modern data warehouses and semantic models. The video uses a hotel warehouse demo to show common pitfalls and practical patterns, and it aims to help designers choose the right approach for their scenarios. Overall, the presentation stresses that the decision is contextual and that surrogate keys remain a useful tool rather than a mandatory rule.
What Guy in a Cube Demonstrates
The video walks viewers through concrete examples where business identifiers work well and where they break down, especially when identities duplicate or change over time. Patrick from the channel shows how relationships in a semantic model behave differently when keys change, and why preserving historical accuracy matters for analytics. As a result, the demo clarifies both conceptual reasons and practical outcomes of choosing one key strategy over another.
Moreover, the demo highlights typical dimensional modeling needs, such as linking facts to the correct version of a dimension when attributes evolve. Here, the presenter explains SCD-style behaviors and how fact tables align to dimension versions, which makes the role of keys more tangible. Consequently, viewers can see tradeoffs in action rather than only reading theory.
When Natural Keys Work — and When They Fail
Guy in a Cube notes that natural keys often perform well for small, stable lookup tables that come from a single trusted source, because they simplify the model and reduce extra columns. However, the video also shows that natural keys can cause trouble when different systems use overlapping identifiers or when business rules change unexpectedly. Therefore, relying solely on natural keys can lead to broken joins and confusing historical reporting.
Furthermore, the presenter explains that natural keys struggle with versioned history: if you need to record attribute changes over time, natural keys can blur which row a fact should reference. In multi-source or merged environments, natural keys risk collision and ambiguity unless you add additional control logic. Thus, the video argues that natural keys are appropriate in constrained cases but not as a universal default.
Why Surrogate Keys Still Matter
According to Guy in a Cube, surrogate keys solve a specific warehouse problem: they provide a stable, internal identifier that does not change with business attributes. This separation lets fact tables point to the exact version of a dimension row, which preserves historical correctness and simplifies reporting. As a result, analytics teams can avoid the brittle joins and mismatched history that natural keys sometimes produce.
In addition, the presenter highlights performance and conformance benefits: compact integer keys often join faster and reduce index size, and they help create conformed dimensions across systems. Yet the video also warns that surrogate keys are not magic; they add operational responsibility to generate and preserve those keys consistently. Therefore, the benefit comes with a cost in pipeline complexity and governance.
Practical Challenges in Modern Platforms
Guy in a Cube points to a current implementation gap in Microsoft Fabric: the Warehouse layer does not natively support auto-increment mechanisms like IDENTITY or SEQUENCE, which complicates surrogate key generation. Consequently, teams must use workarounds such as staged ROW_NUMBER() assignments, dedicated key tables, or controlled merge processes to maintain stable keys across loads. These alternatives work, but they require careful design and testing to avoid duplicate or drifting keys.
Moreover, the video discusses pipeline tradeoffs: generating keys upstream adds complexity to ETL or ELT jobs, while assigning them downstream forces stronger coordination between the warehouse and semantic model. In other words, teams must balance operational overhead against the analytical benefits of stable joins and historical fidelity. The presenter emphasizes that good automation and clear lineage are essential to manage this complexity.
Practical Advice and Tradeoffs for Teams
Guy in a Cube recommends storing the original business key alongside a warehouse surrogate key so that lineage and traceability remain clear. This approach preserves auditability while allowing the model to use stable numeric keys for joins and history. Therefore, teams gain the best of both worlds but must accept the extra storage and pipeline steps required.
Finally, the video urges architects to evaluate needs before choosing a single pattern: use natural keys for small, static domains and adopt surrogate keys where history, conformance, or multi-source integration matter. While surrogate keys improve long-term reliability, they increase operational responsibilities in modern platforms like Microsoft Fabric and Power BI. In short, Guy in a Cube presents a balanced, practical view that helps teams weigh tradeoffs and design robust analytics solutions.
Keywords
surrogate keys, surrogate keys data warehouse, modern data warehouse design, surrogate vs natural keys, data modeling best practices, dimensional modeling surrogate keys, star schema keys, do you need surrogate keys