- All of Microsoft
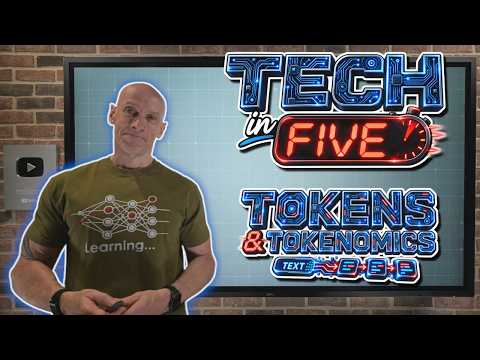
Tech in Five: Tokenomics Demystified
Principal Cloud Solutions Architect
Microsoft expert explains tokens, tokenomics and tokenization, context and cost for AI with Azure OpenAI and PowerShell
Key insights
- Tokens, token limit, and tokenization: Tokens are small pieces of text or data (parts of words, whole words, or punctuation).
Tokenization converts text into these units and a model’s token limit is the max it can read or generate at once. - How models use tokens: Models read a context window of tokens, generate new tokens step by step, and use tokens for reasoning and tool calls.
Every prompt, retrieval, retry, or agent action consumes tokens and affects latency and accuracy. - Token cost and economics: Token consumption directly drives API costs and performance trade-offs.
Hidden costs build up from repeated context, long histories, and frequent tool calls. - Microsoft’s optimization levers: Compress conversation history, cache static context, and route requests to the right model or use a Model Router.
Use tools like Agent Optimizer and select only needed capabilities to reduce input overhead. - Operational best practices: First measure baseline token use, then create a routing matrix and define handoff contracts between agents.
Apply budget guardrails like throttles and circuit breakers to limit unexpected spend. - Business impact and governance: Treat tokenomics as an engineering and governance discipline, not just finance.
Managing tokens helps control spend, preserve quality, and redesign knowledge work for scalable AI adoption.
John Savill's [MVP] latest YouTube entry, "Tech in Five - Tokens & Tokenomics," offers a concise primer on how AI systems use text units and why that usage shapes cost and design decisions. The short video runs through what tokens are, how models turn text into them, and why the amount of token consumption influences both price and user experience. In addition, Savill highlights practical levers that Teams can use to reduce waste and improve performance without sacrificing quality.
What the video explains
The clip begins by defining tokens as small pieces of text or data that models read and generate, and it introduces the idea of a token limit, which caps how much a model can process at once. Savill then walks viewers through tokenization and shows how different words, punctuation, or parts of words translate into one or more tokens. Consequently, the presenter emphasizes that every prompt, response, retrieval, retry, and tool call consumes tokens and therefore affects real costs.
Furthermore, the video links token usage to system design: more context typically means more tokens and higher expense, while not every task needs the most expensive or capable model. Savill uses plain examples to show how repeated content, long histories, and unnecessary model calls create hidden spending and latency. Ultimately, the segment frames token considerations as both an engineering and an operational concern.
How tokens shape system behavior
Savill explains that models generate output token by token and that the available context window constrains reasoning and memory. Thus, larger context windows let models consider more information but come at a cost in computation and billing. As a result, teams must balance context depth against latency and price when designing prompts and workflows.
Moreover, the video points out that not every workflow benefits from the same model: routing simpler requests to smaller models and reserving top-tier models for complex tasks reduces spend while preserving quality. Savill also stresses the value of compressing or caching repeated information so systems do not pay for the same context over and over. In practice, that means choosing where to store static context and when to regenerate or refresh it.
Practical recommendations and tooling
In the short segment, Savill recommends several operational levers that map closely to industry guidance. He highlights compression of conversation history, caching of static context, routing requests by complexity, and using Developer Tools that limit unnecessary input tokens. These steps aim to lower token consumption while keeping responses accurate and timely.
Specifically, the material references features and patterns like Model Router, Agent Optimizer, and Toolbox as examples of how platforms can enforce smarter routing and reduce token overhead. Although Savill does not dive deep into each tool, he underscores the broader point: optimizing the whole stack, not just prompt wording, produces larger and more sustainable gains. Consequently, organizations should instrument token use, measure baselines, and apply guardrails such as throttles or circuit breakers.
Tradeoffs and technical challenges
The video and related commentary recognize several tradeoffs. For instance, compressing history can lower cost but may remove nuance that the model needs for accurate answers, while caching improves speed yet risks serving stale data. Likewise, routing logic reduces expense but adds engineering complexity and operational overhead.
Another challenge involves measurement: teams must quantify token spend across retries, tool calls, and agent handoffs to understand true costs. In addition, designing clear contracts between agents and choosing when to hand tasks back to humans requires careful governance. Therefore, balancing cost, quality, latency, and stability becomes a multidimensional problem that teams must monitor continuously.
Why this matters for organizations
Savill’s summary frames tokenomics as an operating discipline, much like FinOps, that helps organizations treat compute and model calls as resources to manage. By thinking of tokens as a measurable consumption metric, leaders can allocate work between humans and models and set budgets that reflect business priorities. In short, token awareness supports sustainable scaling of agentic AI within enterprises.
Finally, the video is useful for practitioners and decision-makers who need a clear, actionable introduction to token-related tradeoffs. While short, Savill’s piece nudges teams to adopt system-level thinking: measure first, optimize routing and caching, and implement guardrails to keep both cost and user experience under control. As AI becomes more central to workflows, such practical guidance helps organizations balance innovation with predictable economics.
Keywords
tokenomics, crypto tokens, token economics, token design, utility tokens, security tokens, DeFi tokenomics, NFT tokenomics