- All of Microsoft
Fabric Liquid Clustering & Jumpstart
Founder | CEO @ RADACAD | Coach | Power BI Consultant | Author | Speaker | Regional Director | MVP
Microsoft Fabric: Liquid Clustering, Fabric Jumpstart, Direct Lake and Power BI to boost Delta table performance
Key insights
- Liquid Clustering — A Fabric feature that reorders Delta table files so rows with similar values sit together.
It improves query speed by enabling more effective file skipping during selective reads. - Incremental Liquid Clustering & Fabric Runtime 2.0 — Runtime 2.0 includes incremental clustering that reclusters faster and rewrites less data.
Microsoft reports average speed and scan improvements, and the runtime can enable clustering by default for supported tables. - How it differs from Z-Order and partitioning — Liquid Clustering is a declarative, flexible layout approach that avoids rigid Hive-style partitions and manual Z-Order maintenance.
You can change clustering columns without full table rewrites and support high-cardinality columns more easily. - Who benefits and when to use it — It helps teams working with large Delta tables and evolving query patterns, and it can also speed up selective queries on smaller datasets.
Liquid Clustering also supports improved performance for Direct Lake workloads that read files directly. - Operational control and monitoring — Define your clustering columns, let the runtime do layout and rely on auto reclustering to maintain quality as data changes.
Measure impact by tracking file-scan counts, bytes scanned, and query latency to confirm benefits. - Best practices — Choose clustering keys based on common filter patterns, monitor file skipping and scan size metrics, and prefer incremental maintenance over full reorganizations.
Use Fabric Jumpstart or training to adopt patterns and validate designs in your environment.
Episode summary and context
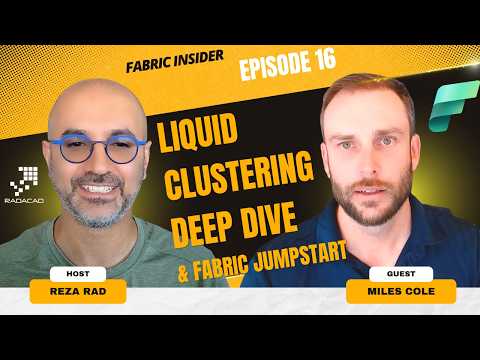
In a recent episode of the Fabric Insider series, host Reza Rad (RADACAD) [MVP] interviews Miles Cole from the Microsoft Fabric team to explain new capabilities in Microsoft Fabric. The conversation centers on Fabric Jumpstart and a technical deep dive into Liquid Clustering, a performance feature for Delta tables in Fabric. This article summarizes the video’s key points and highlights practical implications for data engineers and analysts. Consequently, readers will learn what the feature does, when to use it, and what tradeoffs to expect.
What is Fabric Jumpstart
Fabric Jumpstart appears in the episode as a practical onboarding path for teams adopting Microsoft Fabric. Miles Cole describes it as an accelerator that helps organizations get initial workloads running, while aligning architecture and best practices with Fabric’s capabilities. Thus, it shortens time-to-value and reduces friction during early adoption for teams unfamiliar with Fabric’s unified data and analytics approach.
However, Jumpstart is not a silver bullet for complex organizational issues. While it streamlines initial setup, teams still must decide on governance, data modeling, and operational monitoring. Consequently, the episode stresses the need for human judgment in design decisions even when using prebuilt guidance and templates.
Liquid Clustering explained
The episode frames Liquid Clustering as a declarative layout strategy for Delta tables that reduces the need for manual file layout tuning. Instead of relying solely on static partitioning or manual ZOrder maintenance, users specify clustering columns and the runtime optimizes physical file placement. As a result, queries that filter on clustered columns can skip more files and run faster without heavy manual maintenance.
Importantly, Miles Cole highlights that Fabric treats liquid clustering as a first-class optimization in Fabric Runtime 2.0. The runtime adds features such as Incremental Liquid Clustering and Auto Reclustering, which keep clustering effective as data grows and changes. These mechanisms aim to limit rewrites and maintain clustering quality over time.
Performance gains and practical tradeoffs
Microsoft reports that the optimized implementation of liquid clustering in Runtime 2.0 shows measurable improvements, such as faster clustering operations and fewer files scanned for selective queries. For many workloads, this translates into better query performance and lower operational overhead. Therefore, teams working with large Delta tables may see the most pronounced benefits.
Nevertheless, the conversation also covers tradeoffs. While liquid clustering reduces manual tuning, it can increase background work and storage churn depending on update patterns. In addition, selecting clustering keys remains a critical decision: wrong choices yield minimal benefit and can even worsen small-file behavior. Thus, teams must weigh performance gains against cost, operational complexity, and data ingestion patterns.
Comparing partitioning, ZOrder, and liquid clustering
The episode clarifies that each approach has strengths and weaknesses and that they are not mutually exclusive. Traditional partitioning still helps when queries consistently target a narrow, known key like date, because it limits file metadata and simplifies pruning. In contrast, ZOrder helps colocate multi-dimensional values within files but requires manual maintenance to remain effective.
Conversely, liquid clustering offers adaptability when query patterns are uncertain or evolve over time because it allows clustering columns to change without full rewrites. Yet, when queries always filter on a known, highly selective key, static partitioning can remain more efficient and simpler to reason about. Consequently, the episode recommends evaluating workload patterns and cost constraints before choosing a primary strategy.
Implementation, measurement, and operational advice
Miles Cole and Reza Rad both emphasize measurement and observability when adopting liquid clustering. Teams should monitor file counts, scan metrics, and query latencies to confirm benefits, and they should test clustering keys on representative workloads before wide rollout. Therefore, empirical testing remains the best guardrail against unintended consequences.
Finally, the episode addresses practical controls and future direction. Fabric allows changing clustering columns and supports clustering at various cardinalities, and auto reclustering helps keep layout quality up without constant human intervention. Still, organizations must plan for background processing, cost impacts, and integration with Direct Lake patterns to achieve balanced, long-term performance gains.
Bottom line
The Fabric Insider episode with Miles Cole offers a clear, operational view of how Liquid Clustering and Fabric Jumpstart fit into Microsoft Fabric’s evolving runtime. It presents liquid clustering as a flexible, runtime-driven alternative to rigid partitioning and manual ZOrder, while candidly discussing tradeoffs and measurement needs. As a result, data teams should view this as a useful tool in the toolbox rather than a one-size-fits-all solution.
Overall, viewers seeking to optimize large Delta tables in Fabric will find the episode informative, especially for understanding when incremental clustering and auto reclustering reduce maintenance burden. Yet, the interview also reminds practitioners to test, monitor, and choose strategies that align with workload patterns and cost objectives.
Keywords
Microsoft Fabric Liquid Clustering, Liquid Clustering tutorial, Fabric Jumpstart guide, Fabric Insider Episode 16, Miles Cole Microsoft Fabric, Liquid Clustering deep dive, Microsoft Fabric best practices, Fabric Jumpstart workshop