Azure Database vs Fabric: When to Use
Founder | CEO @ RADACAD | Coach | Power BI Consultant | Author | Speaker | Regional Director | MVP
Microsoft expert dives into Azure SQL, Fabric database, Cosmos DB, migration, Hyperscale and AI for Power BI data pros
Key insights
- Azure databases vs Fabric database: Choose Azure databases for transactional, system-of-record workloads that need mature operational features and independent scaling. Choose a Fabric database when data must immediately join analytics, AI, and Power BI inside a unified, governed platform with fast provisioning and integrated tooling.
- OneLake and integration: Fabric databases connect natively to OneLake, Power BI and Fabric services, simplifying analytics, governance, and sharing. This tight integration reduces ETL work and speeds up scenarios that combine reporting, AI, and real-time analytics.
- Cosmos DB vs Fabric Cosmos: Use Cosmos DB for globally distributed, low-latency, multi-model apps that need fine-grained SLAs. Use the Fabric-hosted Cosmos option when you want those capabilities directly integrated into Fabric’s analytics and governance surface.
- Migration and operational options: Migrations from on-premises SQL Server or Azure SQL can target either Azure or Fabric. Use Fabric mirroring to make operational data available for analytics without large ETL projects. For local/edge needs, consider SQL Server on Azure Local.
- Hyperscale and cost: Hyperscale scales storage and compute to handle very large databases and aims to bill for what you use, but plan for trade-offs between performance, availability, and cost. Compare requirements carefully rather than assuming one provider is always cheaper.
- AI, agentic tools and skills to learn: AI features are appearing across Microsoft databases, plus agentic and developer-first tools that automate tasks. The key skill is combining solid data engineering fundamentals with AI integration—learning how to embed AI and automation into data workflows and apps.
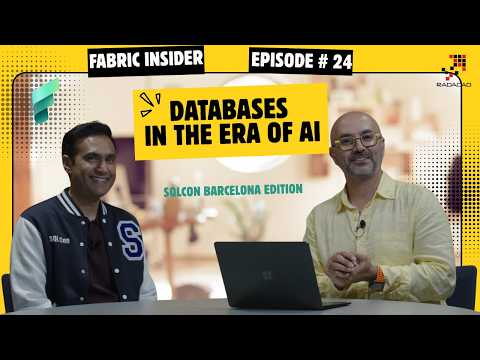
The latest episode of "Fabric Insider," hosted by Reza Rad (RADACAD) [MVP], centers on a practical conversation with Shireesh Thota, Corporate Vice President of Azure Databases at Microsoft. The episode, number 24 in the series, tackles the persistent question many organizations face: should they use Azure databases or the newer Fabric databases? Consequently, the discussion explores migration paths, performance tradeoffs, cost models, and how AI is reshaping database choices for data teams and architects.
Choosing between Azure and Fabric databases
Shireesh frames the decision as one of role and context rather than a simple replacement, and he stresses that both platforms continue to coexist. In general, Azure databases remain best suited for operational systems of record where transactional consistency, predictable SLAs, and independent operational control matter. Conversely, Fabric databases appeal when teams want data to participate immediately in a unified analytics, governance, and AI environment, because they connect natively to services like OneLake and Power BI.
However, choosing between them requires weighing tradeoffs, especially around lifecycle and isolation. For instance, operational teams often prefer the independent scaling and feature depth of dedicated Azure offerings, whereas analytics teams value the lower friction of a database that lives inside Fabric. Therefore, organizations should align their choice with ownership, compliance needs, and the degree to which analytics and real-time insights must be tightly coupled with application data.
Fabric database, Cosmos DB, and integration
The episode clarifies when to pick Cosmos DB inside or outside Fabric, noting that each option suits different application patterns. Cosmos DB shines for globally distributed, multi-model applications that demand low-latency reads and flexible consistency, while Fabric’s database implementations emphasize fast integration with analytics and governance for workloads already in the Fabric ecosystem. As a result, teams should choose based on data distribution needs, latency requirements, and integration priorities.
Moreover, Shireesh highlights that Fabric intends to reduce friction by making databases first-class citizens of the broader data estate. This approach simplifies data movement into analytics pipelines and AI workflows, yet it also introduces design questions about coupling application logic to an analytics platform. Therefore, enterprises must tradeoff immediate integration benefits against the risks of tighter platform dependency and plan a migration or resilience strategy accordingly.
Migration paths, performance, and cost tradeoffs
Many organizations still run on-premises SQL Server or Azure SQL, and Shireesh discusses practical migration approaches that minimize downtime and preserve transactional integrity. He recommends staged strategies such as mirroring for analytics, lift-and-shift where compatibility is high, and refactoring when teams want cloud-native scalability or to exploit Fabric capabilities. In addition, testing and incremental validation reduce operational risk during each migration phase.
Performance comparisons and the role of Hyperscale also feature in the conversation, especially around real-world workload behavior and cost dynamics. While Hyperscale promises large capacity and fast scaling, the episode warns that cost models can become complex in practice, and organizations should carefully model workloads to understand true consumption. Consequently, teams need to balance performance expectations against cost predictability and consider hybrid patterns where operational and analytical workloads scale independently.
Furthermore, migrating to Fabric raises architectural challenges such as handling cross-database transactions, preserving compatibility with legacy features, and maintaining security controls. Teams must also account for governance and monitoring adjustments because a unified platform changes where and how you enforce policies. Therefore, planning should include revalidation of security baselines, performance tests, and operational runbooks.
Database hub, SQL Server on Azure Local, and ecosystem features
Shireesh and Reza also discuss the newly introduced Database hub, which aims to give database managers a single place to discover and manage databases across the Fabric environment. This centralization improves visibility and governance, but it may require teams to change operational workflows and retrain staff to use unified tools. Thus, while the hub simplifies day-to-day management, it also creates transition costs for organizations with established processes.
Likewise, SQL Server on Azure Local addresses edge and latency-sensitive scenarios by bringing familiar SQL Server capabilities close to the application. This option helps teams keep compatibility and control while benefiting from cloud-adjacent deployment models. Still, adopting it involves balancing operational complexity against latency gains and ensuring that distributed management aligns with broader governance rules.
AI, skills, and what data professionals should learn
Finally, the episode turns to AI and the skills data professionals need in this era, and Shireesh argues for a focus on integration and interpretation. Specifically, data teams should learn how to embed AI safely into data pipelines, understand model behaviors, and apply governance to automated actions. Therefore, the key skill becomes the ability to combine domain knowledge with platform capabilities to generate reliable and responsible insights.
In summary, this episode offers a measured view: choose the tool that matches your workload and governance needs, plan migrations carefully, and invest in skills that bridge databases, analytics, and AI. For database administrators, architects, and analytics professionals, the interview provides clear guidance on tradeoffs and practical next steps when evaluating Azure and Fabric database strategies.
Keywords
Azure Database vs Fabric Database, Microsoft Fabric Database explained, Fabric Insider Ep 24 Shireesh Thota, Choose Azure or Fabric Database, Fabric database migration from Azure, Azure vs Fabric database comparison, Shireesh Thota Fabric database insights, Microsoft Fabric database tutorial